01
Clearer Incident Response
Use observability and runbooks to shorten diagnosis and make recovery responsibilities explicit.
Implement modern DevOps practices and SRE principles to increase deployment frequency while maximizing system reliability.
DevOps is not just a job title; it's a culture of collaboration between development and operations, supported by robust automation. Our DevOps and Site Reliability Engineering (SRE) consulting helps organizations break down silos and accelerate their delivery pipelines. We establish Service Level Objectives (SLOs) aligned with business goals, implement comprehensive observability stacks to monitor those objectives, and build the automation required to maintain them. Whether you are struggling with flaky deployments, opaque system performance, or incident response chaos, we provide the architectural patterns and cultural frameworks to achieve high-performance engineering.
A useful engagement connects product intent, engineering choices, quality controls, and operational ownership instead of treating implementation as an isolated hand-off.
Use observability and runbooks to shorten diagnosis and make recovery responsibilities explicit.
Automate repeatable checks and deployment steps according to the risk and release model of the product.
Stop arguing about uptime. Manage reliability mathematically using Error Budgets and SLOs.
Architecture boundaries, integration behavior, security assumptions, and release choices are recorded with their trade-offs.
Documentation, monitoring, access, deployment controls, and next-release priorities are prepared around the operating team.
The first useful step depends on what is already known, what is already running, and which risk needs to be reduced first.
Map your starting pointDevOps is not just a job title; it's a culture of collaboration between development and operations, supported by robust automation. Our DevOps and Site Reliability Engineering (SRE) consulting helps organizations break down silos and accelerate their delivery pipelines. We establish Service Level Objectives (SLOs) aligned with business goals, implement comprehensive observability stacks to monitor those objectives, and build the automation required to maintain them. Whether you are struggling with flaky deployments, opaque system performance, or incident response chaos, we provide the architectural patterns and cultural frameworks to achieve high-performance engineering.
Best fit when
The outcome matters, but scope, dependencies, or the implementation boundary are still uncertain.
Useful outputs
Work proceeds in testable increments that connect interface quality, system behavior, integrations, security, and release readiness.
Best fit when
The direction is understood and you need an accountable path from design through production.
Useful outputs
Use evidence from the live product to prioritize performance, reliability, usability, security, and operating improvements in a controlled sequence.
Best fit when
The current system has value, but specific constraints are slowing users, delivery, or growth.
Useful outputs
What we deliver for DevOps Consulting.
Designing advanced pipelines with progressive delivery, canary releases, and automated rollbacks.
Defining and measuring Service Level Indicators and Objectives that actually matter to users.
Implementing the three pillars of observability: metrics, logs, and distributed tracing.
Setting up PagerDuty/Opsgenie routing, blameless post-mortem templates, and on-call structures.
Reviewing and refactoring Terraform/Pulumi codebases for modularity and security.
The delivery path
How we build scalable solutions from concept to deployment.
Evaluating your current deployment frequency, lead time, MTTR, and change failure rate (DORA metrics).
Working with stakeholders to define critical user journeys and acceptable error budgets.
Deploying observability tools, configuring CI/CD, and writing initial IaC.
Establishing incident management, post-mortem, and deployment review processes.
Training the internal team to operate and evolve the DevOps practices independently.
Where we apply our DevOps Consulting expertise.
Common questions about our DevOps Consulting services.
DevOps is a cultural philosophy that combines development and operations. Site Reliability Engineering (SRE) is a specific implementation of DevOps pioneered by Google, focusing on applying software engineering practices to operations and using math (SLOs/Error Budgets) to manage reliability.
Beyond implementation
Map the people, records, approvals, exceptions, and systems involved before selecting the solution boundary.
Document data ownership, integrations, access, failure handling, deployment, and the trade-offs the team accepts.
Plan validation, rollout, documentation, support, and how the client team will operate the solution after launch.
From the field
Practical notes on modernization, architecture, automation, delivery, and maintainable software systems.
 Product Strategy
A comprehensive master handbook for Product Managers, CTOs, and Founders detailing product discovery cycles, PRDs, RICE scoring, user research, product-led growth (PLG), and agile sprint velocity.
Read article Cyber Security
A comprehensive 5,000+ word technical guide covering OWASP Top 10 mitigations, zero-trust JWT/OAuth auth pipelines, BOLA RBAC guards, Docker/Kubernetes container security, and SOC 2 / ISO 27001 compliance.
Read article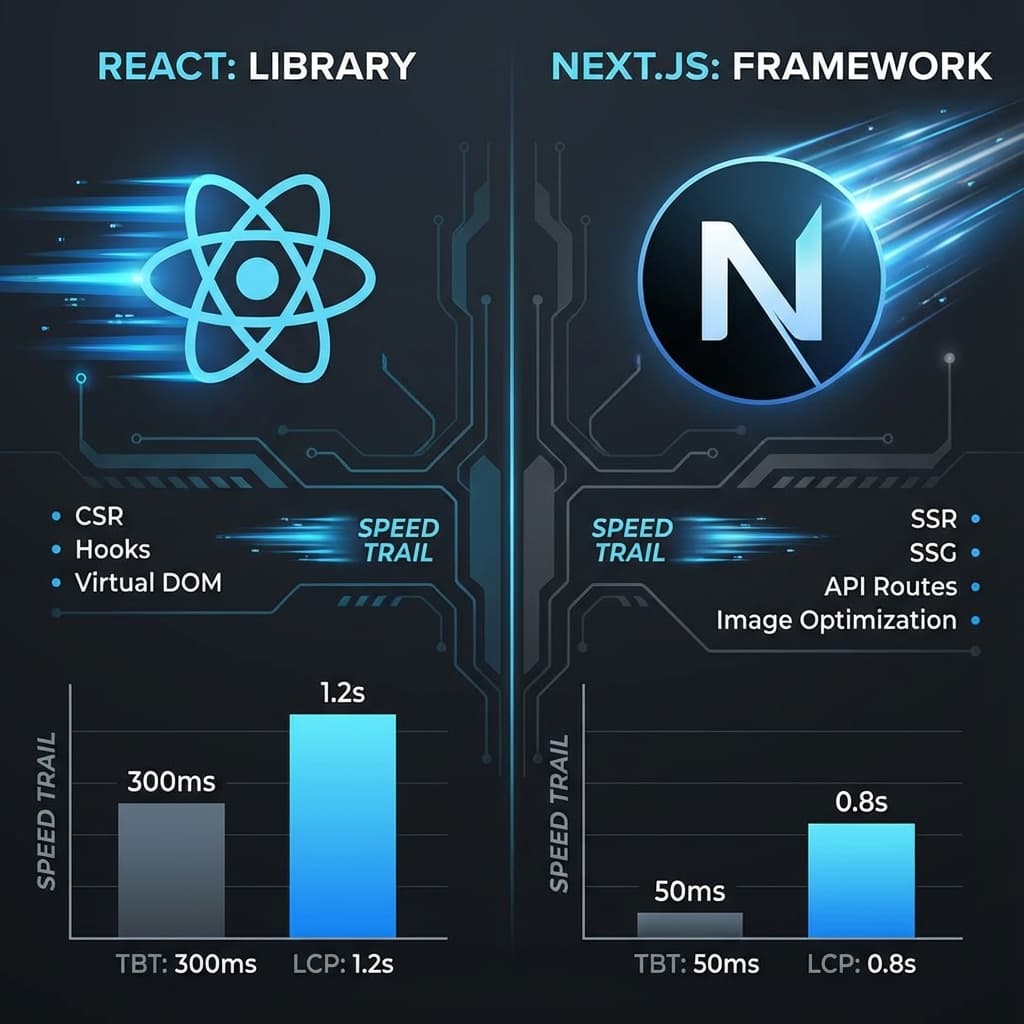 Product Strategy
Product Manager Rohit Sharma outlines strategic frameworks for product discovery, PRD authoring, RICE prioritization, and driving high-velocity engineering delivery.
Read article Product Strategy
How Product Manager Rohit Sharma conducts user research, defines key SaaS metrics (MRR, Churn, LTV/CAC), and aligns engineering roadmaps with business growth.
Read article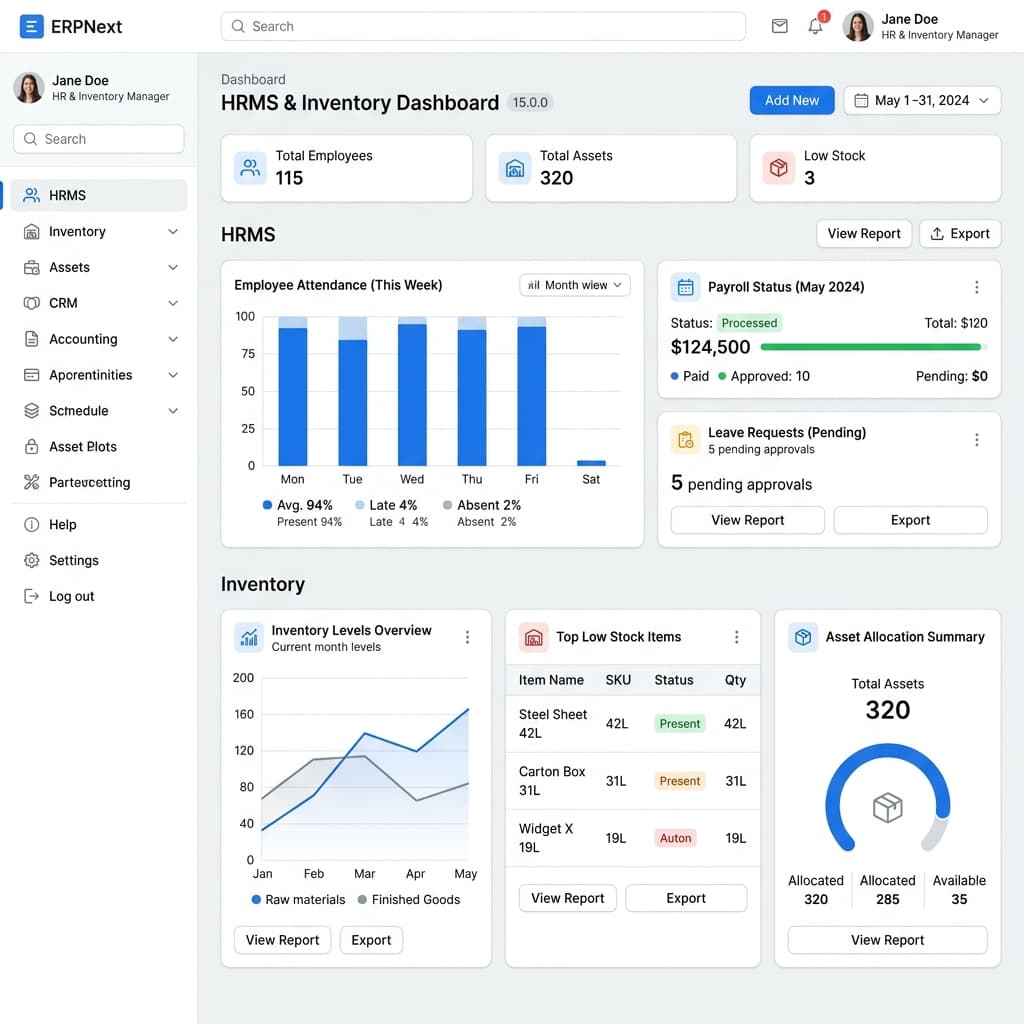 Enterprise Software
A detailed guide on customizing ERPNext to streamline Human Resource Management (HRMS) and Inventory operations. Learn best practices for Frappe, MariaDB, and writing custom server-side scripts.
Read articleExplore other engineering capabilities that complement this service.